08 · proof
Capability and reliability are not the same metric.
pass@k measures whether a case passed at least once in k runs. pass^k measures whether it passed every time. The capability gate requires pass@k ≥ 0.90; the regression gate requires pass^k = 1.0; --gate both requires both. A suite that passes the first and fails the second is flaky, and the report says by how much.
python -m hpp eval run examples/reliable-coding/benchmark-suite.json -k 3 --gate both
python -m hpp benchmark -k 3 --json
Measured: HPP benchmark: pass@k=1.00 · pass^k=1.00 · gate=PASS over ten controls (manifest contract, policy enforcement, WorkGraph waves, lane collision, monitor freshness, context provenance, routing floor, event/evidence gate, graph determinism, evidence attestation), three runs each. The JSON report carries the suite's sha256 and the platform it ran on. Exit 0 when the gate passes, 1 when it does not.
A decision made elsewhere is measured, never trusted by default
New in 2.6.0
The harness calls no model. A small decision taken outside it — by a rule, a person, a local model or a hosted typed-decision model — can be recorded as hpp.decision/v1: always advisory; with raise-only it may raise a declared value and never lower it; abstention and instrument-failure are outcomes that change nothing. hpp decide eval runs the decider you name as a command against labelled cases and reports coverage, selective accuracy, confident errors, abstentions and failures separately, with a coverage curve by confidence floor. Version 1 measures choice questions only.
python -m hpp decide validate decision.json
python -m hpp decide eval examples/typed-decisions/gotcha-family-suite.json --decider-command '["python", "examples/typed-decisions/baseline_decider.py"]'
decide eval SUITE — --decider-command takes the decider's argv as a JSON array of strings, run without a shell; omit it to replay the records stored in the suite's cases, where a case without a record counts as an instrument failure. --timeout (default 10.0) is the number of seconds per case before that case counts as an instrument failure. The gate: --min-selective-accuracy (default 0.9), --max-confident-errors (default 0; a confident error is a wrong answer at or above the suite's confidence_floor, 0.6 when the suite does not set one) and --max-failures (default 0). Exit 0 the gate passed · 1 the gate failed, or nothing was decided and there is no accuracy to measure · 2 an invalid record, suite or argv.decide validate RECORD — prints valid and the effective value a consumer may act on, with its action (raised, kept, advised or none). Exit 0 valid · 2 refused, naming the first broken rule.
Measured from a checkout of main: the baseline decider on the example suite → 15 cases, 12 decided, 3 abstained, 0 instrument failures, coverage 0.8, selective accuracy 1.0, every threshold held, exit 0. The same suite without --decider-command holds no records → 15 instrument failures, no decision was made, exit 1. A record with "authority": "binding" → hpp: authority must be 'advisory': …, exit 2. The 2.5.8 package has no decide command: hpp decide there is an invalid choice, exit 2.
How it works end to end — declaring an advisor such as Jev, pinning its version, recording, validating and measuring it — is in chapter 09. The adapter and its risks are in examples/typed-decisions.
Evidence bundles: the exit code of a criterion, measured outside the model
New in 2.6.0
hpp drives no browser and calls no model. hpp evidence run runs the criterion command you declare — an end-to-end spec, a pytest suite, any script — as argv without a shell, measures its exit code, hashes every artifact file you declared, and writes .hpp/evidence/<id>-<UTC>.json (hpp.evidence/v1): the command, the base commit, the exit code, the verdict, stdout and stderr as byte counts and sha256 (never the text), the artifacts and a self-hash. The verdict is passed only when the command exited 0 and every declared pattern matched a file this run wrote (a file untouched since before the run is listed as unchanged and does not count); otherwise it is failed, missing-artifacts, timeout or could-not-start. hpp evidence verify re-derives a record from the files on disk. The record is self-hashed, and signed only with --sign-key. The self-hash makes an edited record visible; it is not a signature — anyone who can write the file can rewrite it and its hash — so a checker that must not trust the maker re-runs the command from its own lane instead of relying on verify alone, or asks for a signature and checks it with --allowed-signers (optional signature, below).
python -m hpp evidence run --id smoke-page --artifact out/report.html --artifact out/smoke.log -- python examples/evidence/smoke_page.py
python -m hpp evidence verify <record_path>
evidence run --id ID [--artifact GLOB]... -- COMMAND — --artifact is a glob relative to the workspace, repeatable; --timeout (default 600.0) is the number of seconds before the run counts as a timeout; --out is the record directory, relative to the workspace (default .hpp/evidence); --record-event appends evidence_recorded to the event log when, and only when, the bundle passed, and needs at least one --artifact. A secret-like argv, an artifact or --out path outside the workspace, a bad id or a non-positive timeout is refused before anything runs. Exit 0 passed · 1 not passed · 2 refused, or the event could not be appended.evidence run ... --sign-key KEY --signer NAME (new in 2.10.0) — signs the record; --signer is required with --sign-key, and both are checked before the command runs.evidence verify RECORD — the record_path that run printed; --allowed-signers FILE (new in 2.10.0) also demands a signature that file accepts. Exit 0 valid, an intact record of a run that passed · 1 not-evidence, an intact record of a run that did not pass · 2 blocked, the record was edited or contradicts itself, or an artifact changed or went missing, or — with --allowed-signers — the signature is missing, not accepted or over changed bytes.
Measured from a checkout of main, in a copy of the tree so that out/ and .hpp/ were written there: the demo → passed, exit 0, and verify on its record → valid, exit 0. With --break after the script, both artifacts were written and the verdict was failed, exit 1; verify on that record → not-evidence, exit 1, and on a copy edited to read passed → blocked, the record was edited after it was written, exit 2. The first record, verified again after the second run had rewritten out/ → blocked, 2 artifact(s) changed since the run, exit 2: end-to-end runners that clear their output directory at the start of each run do the same, so give artifacts that must stay verifiable a per-run directory. --record-event with no work_started in the log → exit 2, the event not appended; after event append --type work_started it moved the loop to evidenced. The 2.5.8 package has no evidence command: hpp evidence there is an invalid choice, exit 2.
New in 2.7.0: hpp evidence mutate --id ID (--mutants FILE | --generate FILE)... -- COMMAND asks whether the criterion would notice broken code. It runs the command on a copy of the workspace, clean (it must pass, or the verdict is no-control, exit 2, and no mutant runs), then once per mutant (it must fail). --generate mutates a Python file operator by operator (==↔!=, <↔<=, >↔>=, and↔or, True↔False), never inside strings or comments; --mutants reads declared {id, file, find, replace}. Exit 0 sensitive · 1 blind-spots, incomplete or no-mutants · 2 no-control or refused. Measured on examples/criterion-sensitivity: the strong check kills 3 of 3 mutants, exit 0; the weak check, just as green, lets 3 of 3 through and names them, exit 1.
See examples/evidence for the same pattern around a real end-to-end runner.
Retrieval ruler: the retriever, measured apart from the answer
New in 2.6.0
The harness runs no index and calls no model. A retriever is a command you declare: it reads {"query": …, "k": …} as JSON on stdin and prints ranked ids, best first. hpp retrieval eval scores the top k of each answer against the ids an hpp.retrieval-suite/v1 suite labels relevant — hit@k, recall@k, precision@k, MRR and nDCG@k — and counts instrument failures (could not start, timeout, non-zero exit, output that is not JSON, a duplicate id) apart: they are never scored, and the means cover measured cases only. With no measured case the metrics are null and the gate says why, never 0%. Whether a good answer can be generated from what was retrieved is a separate question, not asked here.
python -m hpp retrieval eval examples/retrieval/suite.json
python -m hpp retrieval eval examples/retrieval/suite.json --retriever-command '["python", "examples/retrieval/keyword_retriever.py"]'
retrieval eval SUITE — --retriever-command takes the retriever's argv as a JSON array of strings, run without a shell; omit it to replay the results stored in the suite's cases. -k overrides the suite's cut-off. --timeout (default 10.0) is the number of seconds per case before that case counts as an instrument failure. The gate: at least one measured case, --min-recall (default 0.8) for mean recall@k and --max-failures (default 0). Exit 0 the gate passed · 1 the gate failed · 2 a refused suite or argument.
Measured from a checkout of main: both commands → 7 cases measured, 0 instrument failures, mean recall@3 0.786, hit@3 0.857, MRR 0.786, nDCG@3 0.749, mean recall@k 0.786 < 0.8, exit 1 — the keyword baseline misses the paraphrased question entirely, a measured 0, and the default gate fails; with --min-recall 0.75 → every threshold held, exit 0. A retriever that exits 3 on every case → 7 instrument failures, metrics null, no case was measured (7 instrument failures); there is no recall to measure, exit 1. --retriever-command '"python"' → hpp: --retriever-command must be a JSON array of strings (argv, no shell), exit 2. The suite is synthetic and its baseline was written beside it: these numbers prove the ruler works, not that any retriever is good. The 2.5.8 package has no retrieval command: there it is an invalid choice, exit 2.
See examples/retrieval for the retriever contract and the suite format.
Citation check: every marker resolves, or the exit code says which does not
New in 2.6.0
An answer written from sources marks each claim with the id of the source it rests on — [ID:<id>] by default. hpp cite check reads the answer and the list of context items it was written from, and reports without a model: a marker whose id is not in the context (UNKNOWN_ID), a marker naming a range or a list (RANGE) and an empty marker (EMPTY_MARKER) block; more than --max-per-sentence markers in one sentence (TOO_MANY) and a sentence with a number, percentage, currency amount or date and no marker (UNCITED_CLAIM) warn. It proves that every marker resolves, not that the cited source supports the sentence: that judgement needs a reader. The sentence splitter and the number detector are heuristics, listed in the docstring of hpp/citations.py.
python -m hpp cite check --text examples/citations/answer.md --context examples/citations/context.json
cite check --text FILE --context FILE — --context is a JSON list of items with an id (and their text), or of bare ids; --max-per-sentence (default 4); --marker takes a regex with exactly one capture group, the id. Empty text, text that is only code, secret-like text or context and an unusable regex are refused. Exit 0 clean · 1 warn (TOO_MANY, UNCITED_CLAIM) · 2 block (UNKNOWN_ID, RANGE, EMPTY_MARKER) or refused input.
Measured from a checkout of main: the shipped answer → verdict ok, 7 sentences, 5 markers, 4 of the 5 context ids cited, exit 0. In copies of it: [ID:glossary] changed to [ID:glossary-v2] → UNKNOWN_ID, exit 2; to [ID:runbook-7,sla-2026] → RANGE, exit 2; the marker removed from the sentence with 4 engineers → UNCITED_CLAIM, exit 1. And the limit, measured: 42 minutes changed to 90 minutes, still cited to the source that says 42 → verdict ok, exit 0. The 2.5.8 package has no cite command: there it is an invalid choice, exit 2.
See examples/citations for another marker syntax and the report format.
House Session: a panel of pinned deciders, counted, stopped and sealed
New in 2.7.0
The harness calls no model: the seats and the judge answer outside it, in their own lanes. hpp deliberate checks what they said. A panel (hpp.panel/v1) does not start unless every seat names a pinned model (an alias such as -latest is refused), the participants come from at least two model families, exactly one judge sits in a lane no participant uses, and the roles fit the session_type — a review needs two examiners and a dissenting seat. Each turn (hpp.turn/v1) lists the turns its seat had read: a round-1 turn that read any is refused, so the blind round is checkable. A seat with no turn in a round is not judged, never a vote against, and it blocks the verdict. The session stops by rule — not-judged, grounded-convergence, paused-budget, no-new-evidence, max-rounds — and escalate sends grounded dissent that survived to a person. record seals the panel, the turns, the tally, the stop, the judge's hpp.decision/v1, the verdict and the dissent that lost into hpp.deliberation/v2 (the form sealed since 2.8.0; a v1 record is only verified); verify checks the seal and re-derives the tally, stop and verdict from the turns. The seal is not a signature: a consistent rewrite of a turn or of the judge's record, resealed, verifies, so keep the verbatim text and the judge's raw response, whose hashes the record carries. A session ends at the first round where a rule holds; turns of later rounds are refused, and the judge's record must come from the judge seat's provider and pinned model. The human decision is written afterwards, outside the seal.
New in 2.8.0: a panel may declare evidence.ids — plan --context FILE fills them from the context the seats were given, --evidence RECORD... adds each hpp.evidence/v1 record that verifies. Then a fact grounds a position only through a reference that resolves; any other reference is unsupported, listed per round and never counted as new evidence. When the verdict leaves grounded dissent standing, record needs --rationale, an hpp.rationale/v1 from the judge seat with one steelman per dissenting position and at least one would_change_if. The record is hpp.deliberation/v2; a v1 record sealed by 2.7.0 still verifies.
New in 2.8.0, in the lane module: house_session.py families says whether the host can seat two model families (one is DEFERRED, never a one-family panel), and house_session.py seat runs one seat's command in its own worktree, fingerprinting the worktree before and after — a seat that wrote gets no turn (exit 2), a seat that failed is not judged (exit 1). /deliberate in Claude Code and the house-session skill in Claude Code and Codex walk the whole session.
python -m hpp deliberate plan examples/house-session/review/panel.json
python -m hpp deliberate stop --panel examples/house-session/review/panel.json --turns examples/house-session/review/turns.json
python -m hpp deliberate record --panel examples/house-session/review/panel.json --turns examples/house-session/review/turns.json --judge examples/house-session/review/judge.json --rationale examples/house-session/review/rationale.json --out out/record.json
python -m hpp deliberate verify out/record.json
deliberate plan FILE [--context FILE] [--evidence RECORD...] [--out FILE] · deliberate validate FILE [--panel FILE] — validate reads a panel, a turn (with the panel it belongs to) or a record, which it verifies. Exit 0 valid · 2 refused, naming the first broken rule.deliberate tally --panel FILE --turns FILE · deliberate stop --panel FILE --turns FILE — --turns is a JSON list of hpp.turn/v1. Exit 0 reported · 2 refused.deliberate record --panel FILE --turns FILE [--judge FILE] [--rationale FILE] --out FILE — refuses a session that has not stopped, a verdict without a judge, a verdict over grounded dissent without a steelman, and a judge that answered another question, another state or from another model than the judge seat's. Exit 0 sealed with the judge's answer · 1 sealed, verdict blocked or judge failed · 2 refused.deliberate verify RECORD — exit 0 intact · 2 broken: edited after sealing, or it does not re-derive from its own turns and judge.
New in 2.9.0: a sealed session feeds the commands that act on a verdict, and can only make the outcome stricter. hpp route --deliberation PLAN-RECORD --maker-family F lets a plan session raise the request's risk, never lower it. hpp attest create ... --deliberation GATE-RECORD --maker-family F is the release gate: a release-gate session whose facts rest only on hpp.evidence/v1 records; the attestation records the stricter verdict and the record hash, and a panel that did not decide sends it back for revision. lane_board.py select --deliberation DESIGN-RECORD decides a competition, with the judge as the reviewer of record. A judge of the maker's model family is refused everywhere.
Measured from a checkout of main: the review example → stop max-rounds, escalate: true; record → verdict high, dissent seat c at low, blind agreement 0.33, final agreement 0.67, 591 characters of 6000, exit 0; verify → intact, exit 0, and on a copy with the verdict edited → record_sha256 does not match, exit 2. record without --judge → a verdict needs the judge's decision record, exit 2. The panel replayed as one decider on the typed-decision suite → 15 sessions, 12 decided, 3 abstained, 0 instrument failures, exit 0. The sessions are synthetic: they prove the contract, not that a panel beats one agent.
See examples/house-session for the roles each session type needs and the full stop rule.
Attestation binds an approval to bytes
hpp attest create records a verdict together with the spec hash, the base commit, a digest of the full repository snapshot (tracked and untracked), the maker, the checker and the session. Maker and checker must differ, or the record is refused. hpp attest verify re-derives every binding and blocks when any of them moved.
python -m hpp attest create --repo . --spec spec.md --output att.json --maker a --checker b --session s1 --verdict approved
python -m hpp attest verify att.json --repo .
Measured in a scratch repository: --maker a --checker a → hpp: maker and checker must be different non-empty actors, exit 2. With different actors the record is approved and verify returns valid, exit 0; after one line of the spec changed, verify returns blocked with mismatches: spec_sha256, snapshot_digest, exit 2. Attestation requires git.
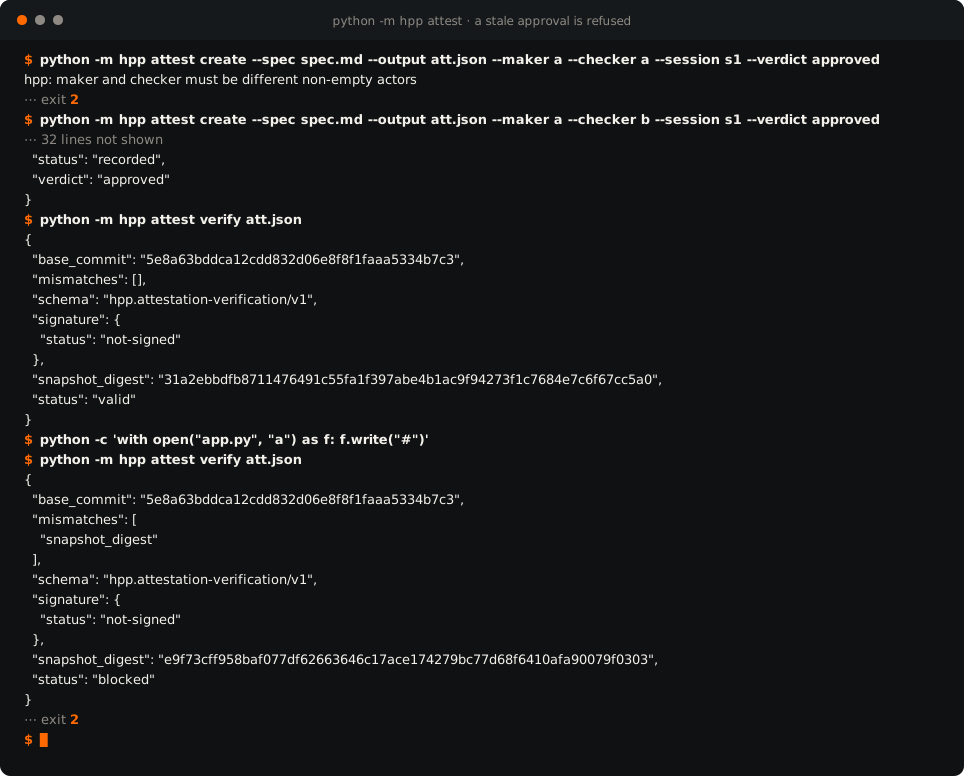
Rendered from a live run (scripts/render_terminal_svg.py --animate --session attest): in a repository whose one commit holds spec.md and app.py, one byte appended to app.py after the approval makes verify return blocked with mismatches: snapshot_digest alone, exit 2, while base_commit does not move: an uncommitted edit moves the snapshot, not the commit.
Optional signature: who gave the verdict, checked offline
New in 2.10.0
A self-hash shows that a record changed; it does not say who wrote it. Both records can carry an SSH signature. attest create ... --sign-key KEY [--signer NAME] signs the attestation — the signer defaults to the checker — and evidence run ... --sign-key KEY --signer NAME signs the evidence record. The harness never reads the key: it runs ssh-keygen -Y sign, namespace hpp, over the canonical bytes of the record — the signature itself never among them — and stores a signature block — scheme (sshsig), namespace, signer, the sha256 of the signed bytes and the armored signature. Without ssh-keygen on PATH the command refuses (exit 2) and nothing is written.
attest verify and evidence verify report the signature in their own signature block. Without --allowed-signers it is not-signed or not-verified (present, never claimed), and the verdict is decided exactly as before. With --allowed-signers FILE — the ssh-keygen allowed-signers file the verifier trusts — it is verified only when ssh-keygen -Y verify accepts the signature of exactly these bytes by a key the file lists for the signer named; anything else is refused, and the record is blocked, exit 2: unsigned, signed by another key, or changed after signing, however consistently its hash was recomputed.
python -m hpp attest create --repo . --spec spec.md --output att.json --maker a --checker b --session s1 --verdict approved --sign-key ~/.ssh/id_ed25519
python -m hpp attest verify att.json --repo . --allowed-signers allowed_signers
python -m hpp evidence run --id smoke --artifact out.txt --sign-key ~/.ssh/id_ed25519 --signer b -- python check.py
python -m hpp evidence verify <record_path> --allowed-signers allowed_signers
Measured on the 2.10.1 source tree in a scratch repository, with an ed25519 key and an allowed-signers file listing it for the checker, the signed attestation: verify without the file → valid, signature not-verified, exit 0; with the file → valid, signature verified, exit 0; with a file listing another key → blocked, mismatches: signature, exit 2. An unsigned attestation verified with the file → blocked, the record is not signed, exit 2. evidence run --sign-key without --signer → hpp: signing needs a signer: pass --signer with the principal your allowed-signers file lists, exit 2; with it → passed, and evidence verify answers not-verified, verified and blocked exactly as the attestation did.
See the claim matrix and the benchmark contract.